Why Tractability Matters
Computer science is not only about whether a problem can be solved at all, but also about whether it can be solved with realistic amounts of time and memory. That distinction matters because a program that takes a millisecond on 100 items may take centuries on a much larger instance if its running time grows too quickly.
Consider two familiar tasks. Sorting a list of a million numbers is routine because efficient algorithms scale well enough to handle large inputs. By contrast, trying every possible route through many cities in a travel-planning problem grows so fast that brute force quickly becomes useless.
This is the heart of tractability: not just “can a computer solve it?” but “can a computer solve it before the universe gets old?” That is the question complexity theory turns into mathematics.
What is a Computational Problem?
A computational problem is a general task defined by the relationship between valid inputs and the outputs that should be produced. An algorithm is a specific step-by-step method for solving that problem.
For example, “sort this array” is a problem, while merge sort and quicksort are algorithms for that problem. “Find the shortest path between two nodes in a graph” is a problem, while Dijkstra’s algorithm is one solution method for certain versions of it.
This distinction matters because complexity theory classifies problems, not just programs. If one clever algorithm is slow but another is fast, the problem may still be tractable because at least one efficient algorithm exists.
Input Size and Output Size
To talk about efficiency, a notion of problem size is needed. Complexity theory usually measures resources as a function of the input length, often counted in bits, though in practice the size may also be described as the number of elements in a list, the number of vertices and edges in a graph, or the length of a string.
Take a sorted-phonebook search. If the input is a list of names, the natural input size might be the number of entries, written as n. If the input is an integer, the size is more naturally the number of bits needed to write that integer, not the number itself.
Output size can matter too. If a problem asks for all valid solutions rather than one solution, the output itself may be enormous. This is one reason complexity discussions often focus carefully on the exact formulation of the problem.
Computational Resources
The main resources studied in complexity theory are time and space: how many computational steps an algorithm uses, and how much memory it needs. Most introductory discussions focus on time because it is the most intuitive measure of whether a problem feels easy or hard.
For example, an algorithm that scans a list once uses time roughly proportional to the list length. An algorithm that compares every pair of elements uses much more time, and an algorithm that tries every subset of elements can become impossible to run for even moderate input sizes.
Other resources also matter in advanced theory, including randomness, parallelism, communication, and circuit depth. Still, time complexity is the central lens for understanding tractability.
Big-O Notation and Growth Rates
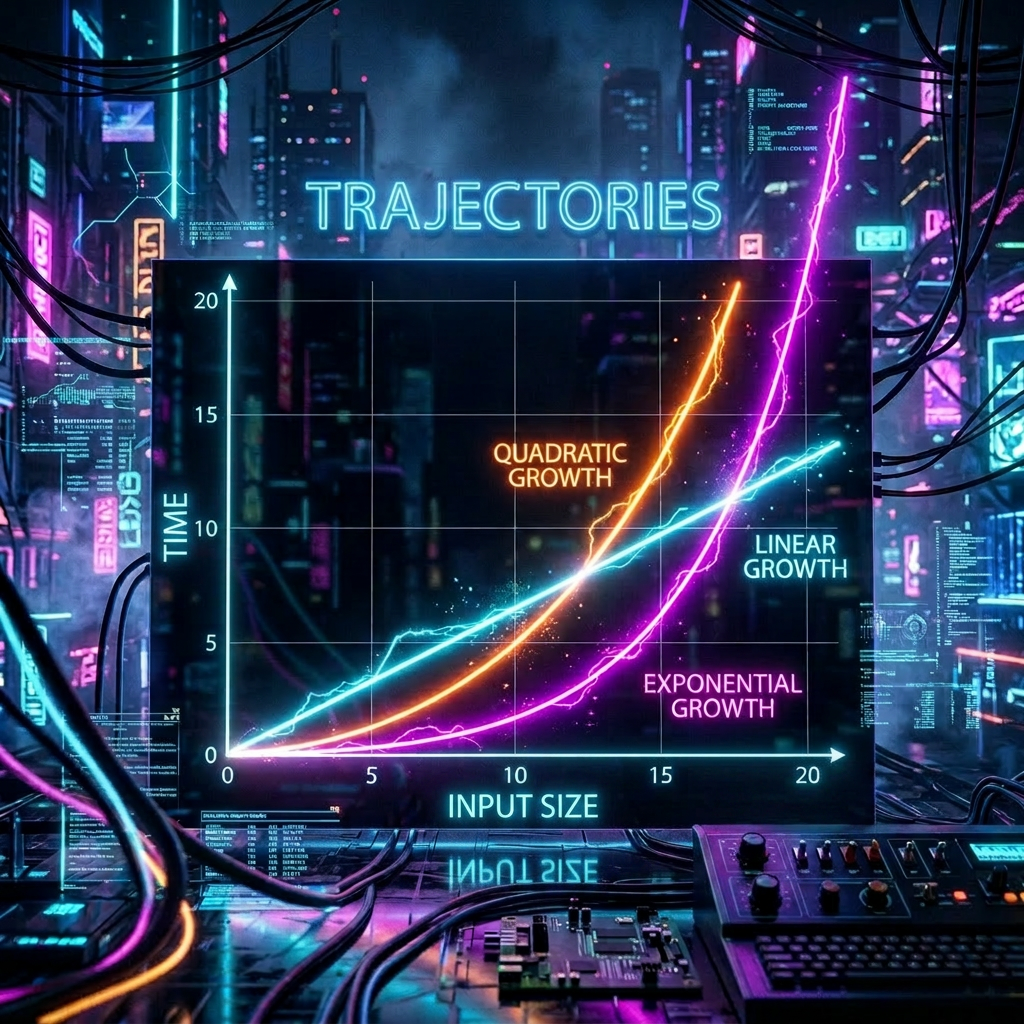
Big-O notation describes how an algorithm’s resource usage grows as the input size increases. It suppresses constant factors and lower-order terms so the long-run growth pattern is easier to see.
If one algorithm takes steps and another takes , Big-O notation records them as and . That simplification is useful because for large enough , the growth rate matters more than small implementation details.
A few common growth rates appear again and again:
- : constant time, such as reading one array element by index.
- : logarithmic time, such as binary search in a sorted array.
- : linear time, such as scanning a list once.
- : log-linear, common in efficient sorting algorithms.
- : quadratic time, such as checking all pairs.
- : exponential time, such as trying all subsets of an -element set.
An intuitive example helps. If a quadratic algorithm handles 1,000 items, then scaling to 10,000 items increases the work by roughly 100 times, not 10 times. For exponential algorithms, the blow-up is even worse: adding just one more input element may nearly double the work.
From Algorithms to Complexity
The complexity of an algorithm is a function describing how its resource usage depends on the input size. In practice, this often means counting the number of key operations in the worst case.
Suppose an algorithm searches an unsorted list for a target value. In the worst case, it examines every item, so its time complexity is . If another algorithm checks every pair of items for a duplicate sum, its running time may be .
Complexity theory often emphasizes worst-case analysis because it provides a clear and robust guarantee. Average-case analysis can also be important, but it depends more heavily on assumptions about the input distribution.
The Intuitive Idea of Tractability
Informally, a tractable problem is one that remains manageable as the input grows, while an intractable problem becomes unmanageable too quickly. This is not a statement about whether a problem is annoying for us humans; it is a statement about how resource requirements scale for algorithms.
For instance, checking whether a number appears in a sorted list is tractable because efficient methods such as binary search scale gently with input size. In contrast, many combinatorial search problems, like trying all assignments in a large constraint puzzle, explode in size because the number of possibilities grows exponentially.
This informal distinction is useful, but complexity theory wants a sharper boundary. That leads to the formal idea of polynomial time.
A Formal View: Polynomial Time
The standard formal benchmark for efficiency is polynomial time: running time bounded by for some constant . This idea is often associated with Cobham’s thesis, which treats polynomial-time solvability as the right mathematical notion of feasible computation.
Why polynomial time? One reason is robustness. Polynomial bounds are relatively stable across many reasonable machine models, while fine-grained differences such as 1 second versus 10 seconds depend much more on hardware and implementation details.
Polynomial time is not the same as “fast in practice.” An algorithm with complexity is polynomial but useless, while a small exponential algorithm may be practical for tiny inputs. Even so, polynomial time is the main dividing line because it captures scalable efficiency better than raw wall-clock time.
Tractable Problems
A problem is usually called tractable if it has at least one polynomial-time algorithm. These are the problems that complexity theory treats as efficiently solvable in principle.
Examples include:
- Sorting numbers, which can be done in time with standard comparison-based algorithms.
- Searching a sorted array with binary search in time.
- Finding shortest paths in many graph settings using polynomial-time algorithms such as Dijkstra’s algorithm or Bellman-Ford, depending on edge constraints.
- Computing a minimum spanning tree in a weighted graph with algorithms such as Kruskal’s or Prim’s.
- Matrix multiplication for naive implementations is polynomial time with .
These examples are useful because they show that tractable does not mean trivial. Some tractable problems are conceptually deep, but they still admit algorithms whose growth stays under control.
Intractable Problems
A problem is usually called intractable when no polynomial-time algorithm is known and the best known exact methods require super-polynomial time, often exponential time. In practice, that means input growth destroys solvability much faster than hardware improvements can compensate.
A classic example is the Traveling Salesperson Problem (TSP) in its optimization form: given distances between cities, find the shortest tour visiting each city exactly once and returning to the start. Brute force considers an enormous number of possible tours, and that number grows explosively with the number of cities. The brute force algorithm requires factorial time, which is the pathological case for complexity theory with .
Other familiar examples include satisfiability problems, subset-style combinatorial searches, and many hard scheduling and packing problems. These problems are often solvable for small instances, but exact solutions become impractical surprisingly quickly.
Complexity Classes
A complexity class is a collection of problems grouped by the resources needed to solve them. Classes help organize the landscape of computational difficulty.plato.stanford+1
The most famous classes in introductory complexity theory include P, NP, NP-complete, NP-hard, and EXPTIME. They do not capture every subtlety of computational difficulty, but they provide a powerful map for understanding tractability and hardness.balaramshiwakoti+3
One helpful way to think about complexity classes is as neighborhoods in a city map. Problems in the same class are not identical, but they share broad structural constraints on how hard they are to solve.
P: Efficiently Solvable Problems
P is the class of decision problems solvable in polynomial time by a deterministic machine model. A decision problem is one whose answer is simply yes or no.
For example, “Is there a path from node A to node B?” is a decision problem. “Is this graph connected?” and “Does this sorted list contain the number 42?” are also decision problems, and they can be solved in polynomial time.
P matters because it is widely treated as the formal home of tractable decision problems. When people say a problem is efficiently solvable in complexity theory, they often mean that its decision version lies in P.
NP: Efficiently Verifiable Problems
NP is the class of decision problems whose yes-instances have certificates that can be verified in polynomial time. Informally, even if finding a solution seems hard, checking a proposed solution can still be easy.
Consider Sudoku as an intuition pump, even though formal complexity statements require precise encodings. Solving a large generalized puzzle may be difficult, but if someone hands over a completed grid, checking whether it obeys the rules is straightforward.
Another standard example is SAT, the Boolean satisfiability problem. Given a truth assignment, verifying that it satisfies a Boolean formula can be done efficiently, which places SAT in NP.
NP-hard Problems
A problem is NP-hard if every problem in NP can be reduced to it by a polynomial-time transformation. Intuitively, NP-hard problems are at least as hard as the hardest problems in NP.
This definition does not require the problem itself to be in NP. Some NP-hard problems are optimization problems rather than decision problems, and some may even be harder than anything in NP.
A standard example is the optimization version of the Traveling Salesperson Problem. Its decision variant is closely tied to NP-completeness, while the optimization version is NP-hard because solving it efficiently would also solve a wide range of NP problems efficiently.
It is useful to separate NP-hard from NP-complete. NP-complete problems are the problems that are both in NP and NP-hard, while NP-hard is the broader label
EXPTIME and Clearly Exponential Computation
EXPTIME is the class of decision problems solvable in exponential time, typically bounded by expressions like for some polynomial . These problems can be solved by brute-force-style or systematically exponential procedures, but their running time grows far too quickly to count as tractable.
A common example comes from certain games or logical systems where the state space grows exponentially with the input description. In such settings, exhaustive exploration may eventually solve the problem, but only with astronomical cost.
EXPTIME helps clarify that not all hard problems are merely “probably hard.” Some classes are defined by explicit exponential upper bounds, which makes the growth-rate contrast with P especially stark
Reductions: How Hardness is Compared
Reductions are transformations that convert one problem into another in a way that preserves solvability. In complexity theory, polynomial-time reductions are the standard tool for comparing hardness.
The logic is simple but powerful. If problem A can be transformed efficiently into problem B, and B has an efficient solution, then A also has an efficient solution via that transformation. So if a known hard problem reduces to B, B must be at least that hard.
This is how NP-hardness is established. Rather than proving from scratch that a problem has no efficient algorithm, researchers show that solving it efficiently would also solve many already-known hard problems efficiently.
P vs NP
The P vs NP question asks whether every problem whose solutions can be verified in polynomial time can also be solved in polynomial time. In symbols, it asks whether .
If , then many problems currently treated as intractable would become tractable in the formal sense. If , then efficient verification would remain fundamentally easier than efficient search for some problems.
This question matters far beyond theory. It affects optimization, automated reasoning, scheduling, cryptography, and the limits of what efficient algorithms can achieve.
How Engineers Cope With Intractability
Real systems still have to handle hard problems, so software engineering does not stop where complexity theory says “intractable.” Instead, practitioners use strategies that trade exactness, generality, or worst-case guarantees for usefulness.
Common strategies include:
- Heuristics, which often find good solutions quickly without guaranteeing the best one.
- Approximation algorithms, which provide provable bounds on how close a solution is to optimal for some optimization problems.
- Special-case algorithms, which exploit structure in real-world instances even when the general problem is hard.
- Parameterized methods, which can be efficient when a particular parameter stays small even if the full problem is hard.
A route planner is a good example. The ideal optimization problem may be computationally hard in full generality, but practical systems combine preprocessing, heuristics, geographic structure, and approximation to produce answers that are excellent and fast enough for human use.
Closing perspective
Tractability is one of the most useful ideas in theoretical computer science because it connects abstract mathematics to a practical engineering question: how does difficulty scale? The answer is often more important than whether a small instance can be solved today on a laptop.
That is why complexity theory focuses so much on input size, growth rates, polynomial time, and hardness classes. Together, these ideas explain why some problems become routine infrastructure while others remain stubborn frontiers of research and engineering.
Leave a Reply